Writing
Hi :) this is where I overshare about AI.
10 posts
Fewer clues can help a model generalize. Not every change is safe.
When fewer clues support generalization, and what a finite shortcut diagnostic actually found.
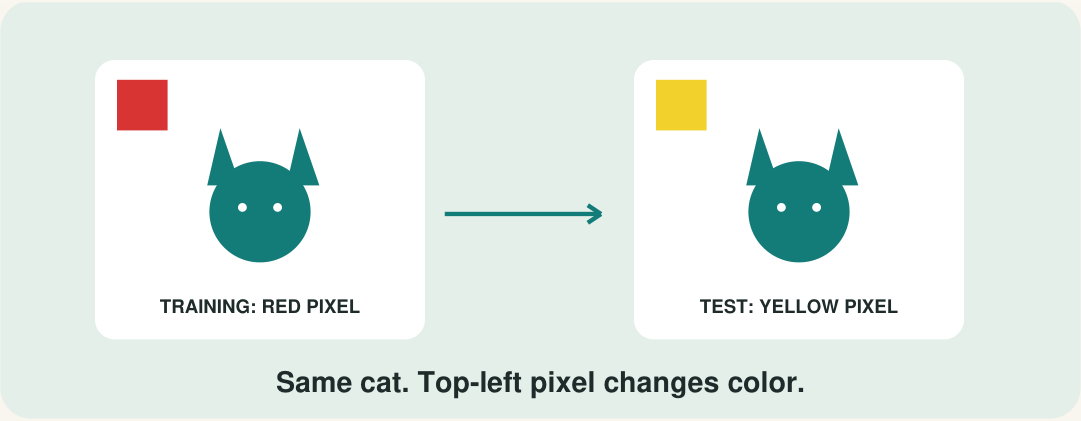
Your model found the right answer. It might never learn to find it again.
What GRPO, a reward-based training method, changes across several tries.
The model weights are open. Can we see how the model learned?
Why open model training matters, and how to test the steps that shape an assistant.
A million tokens can still lose the right document
Why seeing every document is not the same as finding the right one.

The agent did everything right. The website still said no.
What a verifier can learn when the assistant took the right steps but the website failed.

Can one reward teach an assistant everything?
A reading of MAHALO, where accuracy, human values and tutoring pull an assistant in different directions.

The one percent we stopped looking at
Muon, Never Give Up, and the cases an average can hide.

Never Give Up: why easy problems eat the RL budget
A deep dive into the Matthew Effect, and how adaptive sampling gives hard problems another chance.
A coin flip made this model better at math. Or did it?
Notes on "Spurious Rewards", a paper about what RL training really teaches a model.

The polite sentence that broke my model
How we taught small language models to call tools with GRPO, and why the strictest rule worked best.
