Series
30 days, 30 papers.
One paper a day, explained simply.
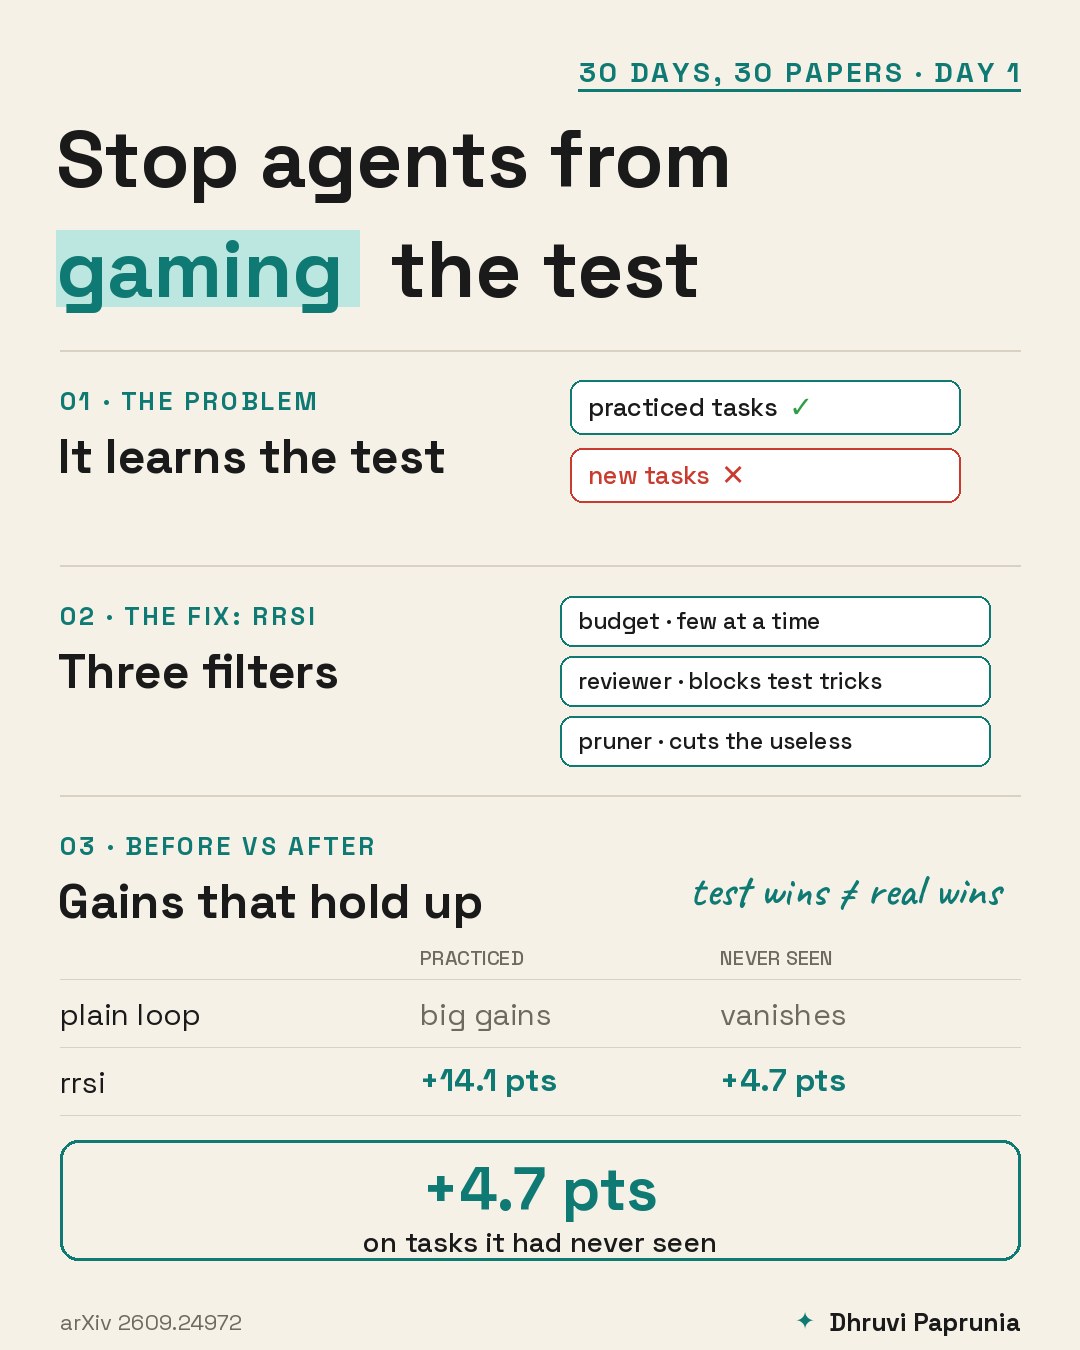
Day 1
Stop agents from gaming the test
RRSI: Regularized Recursive Self-Improvement of Agent Harnesses
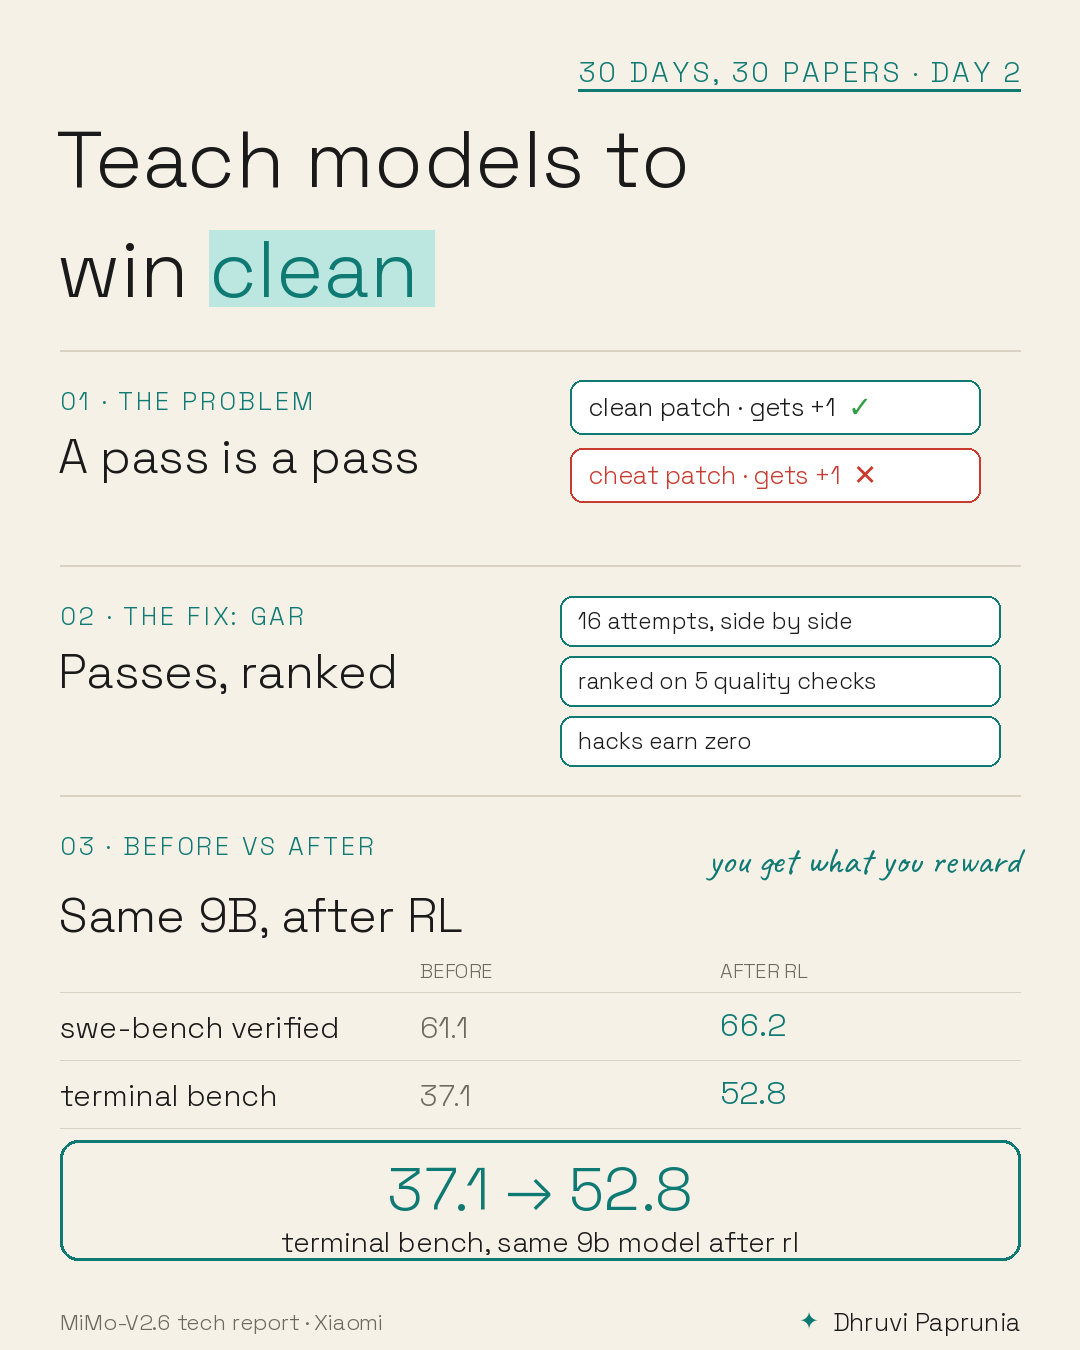
Day 2
Teach models to win clean
MiMo-V2.6: Scaling Up Reinforcement Learning for Self-Improvement
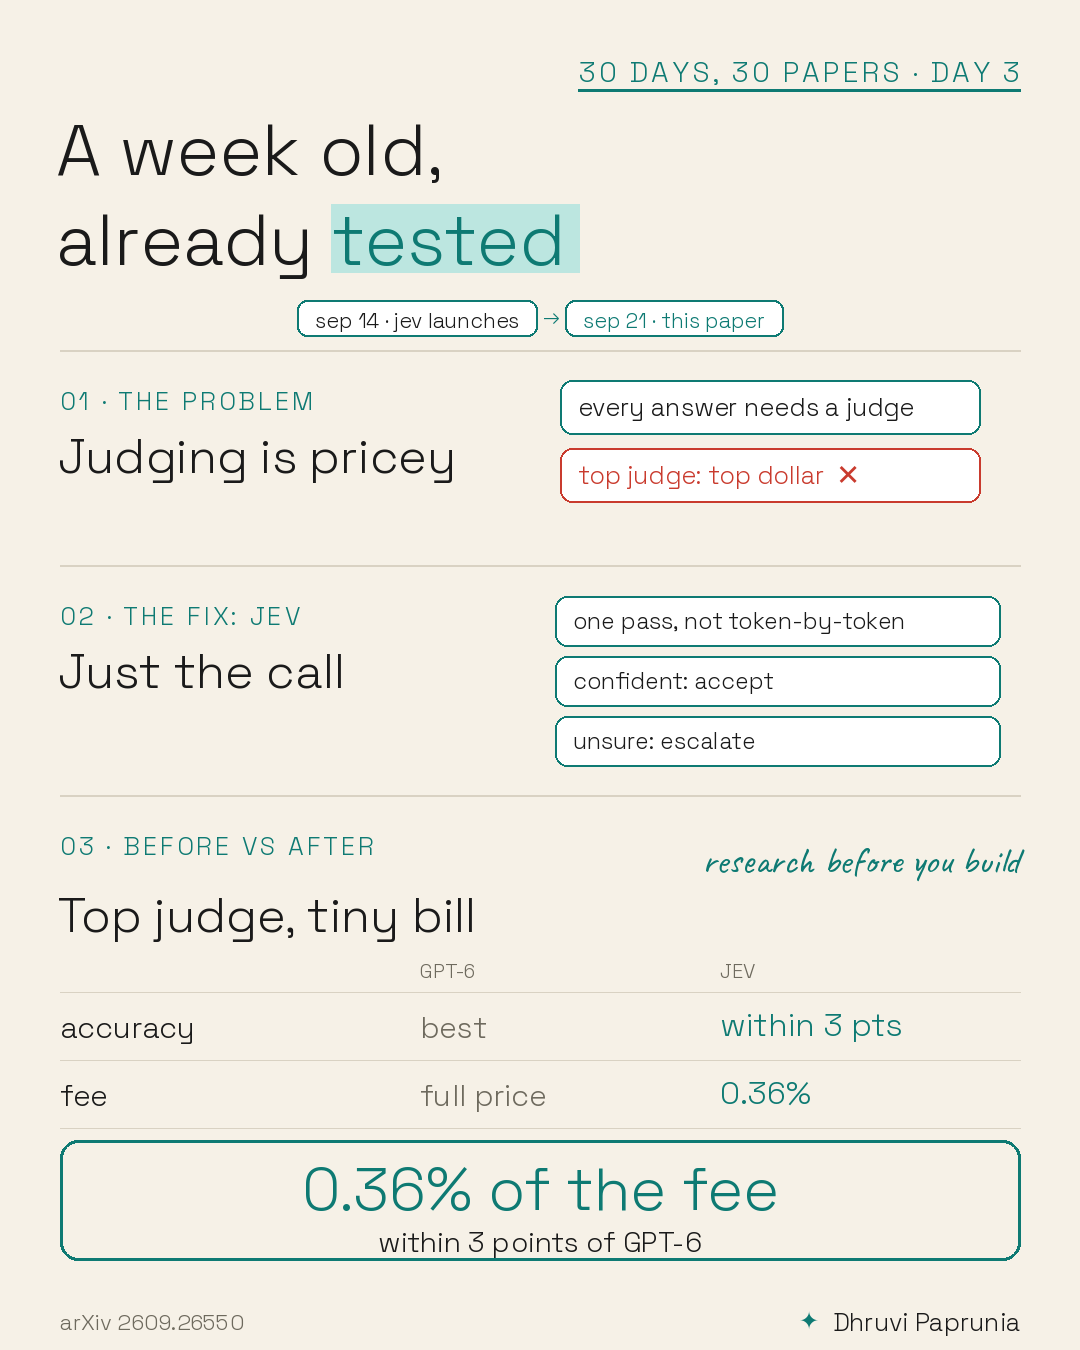
Day 3
A week old, already tested
JEV-as-a-Judge: Accept When Confident, Escalate When Unsure
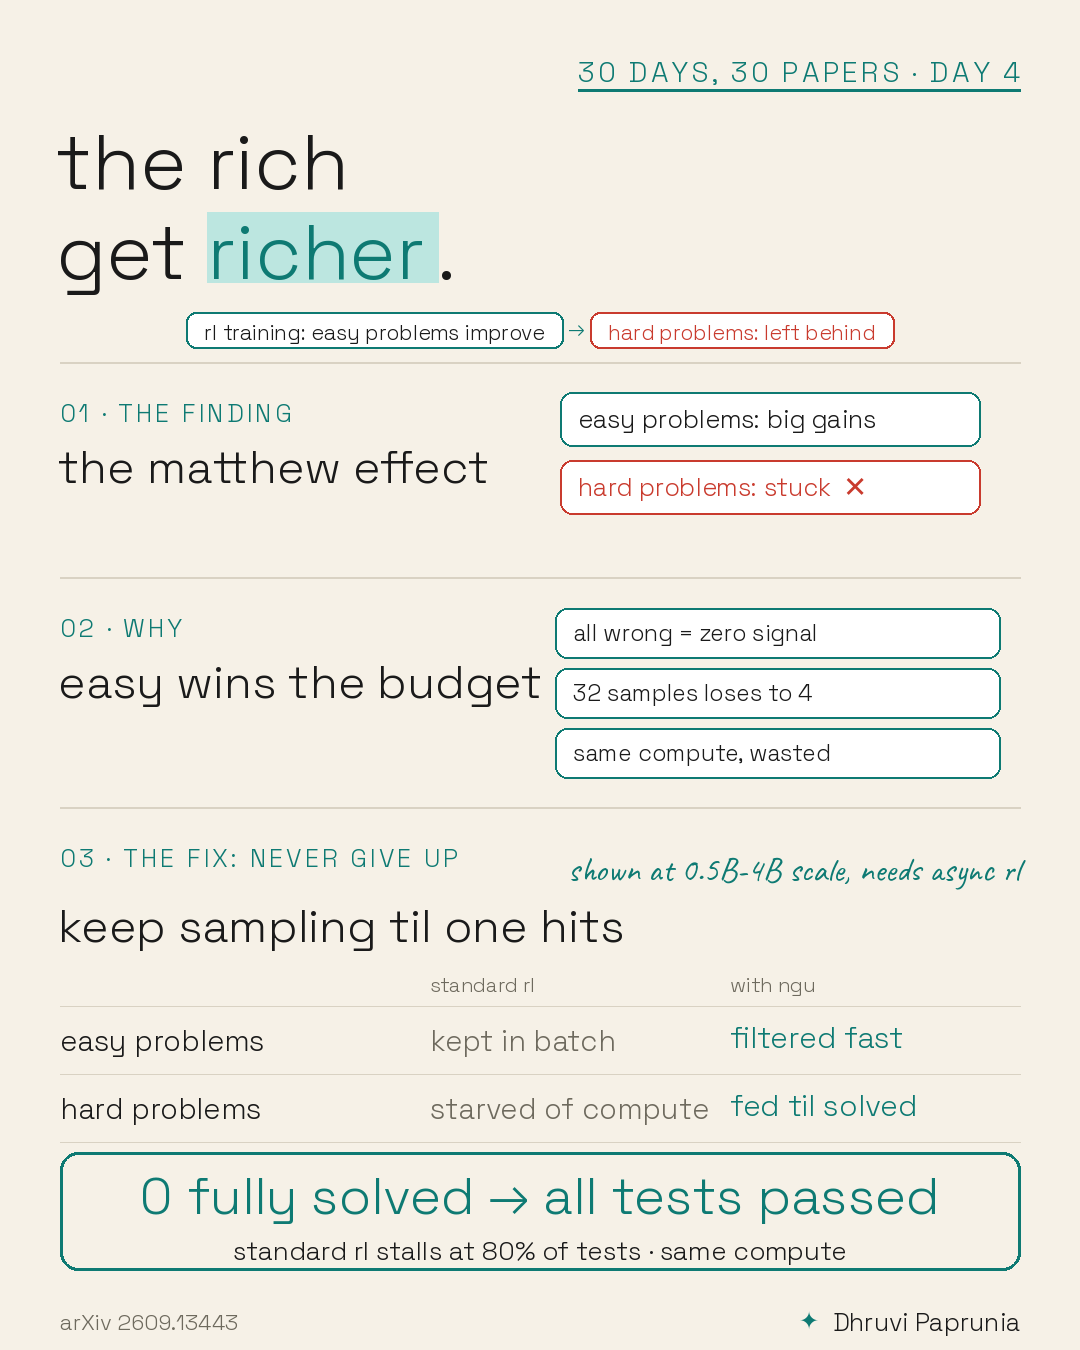
Day 4
The rich get richer
Never Give Up: Learning to Solve Hard Problems in RL for LLMs
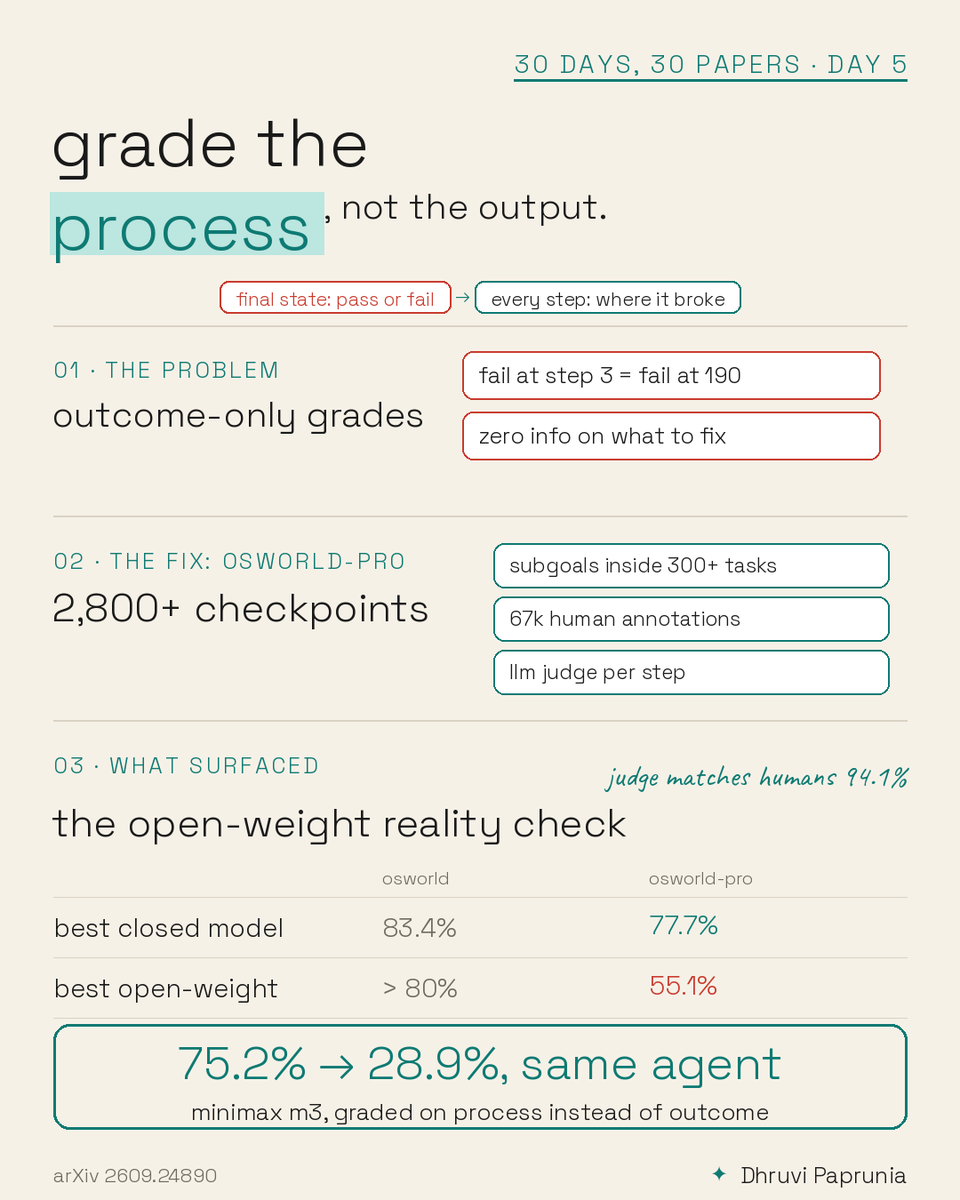
Day 5
Grade the process, not the output
OSWorld-Pro: evaluating where computer-use agents fail
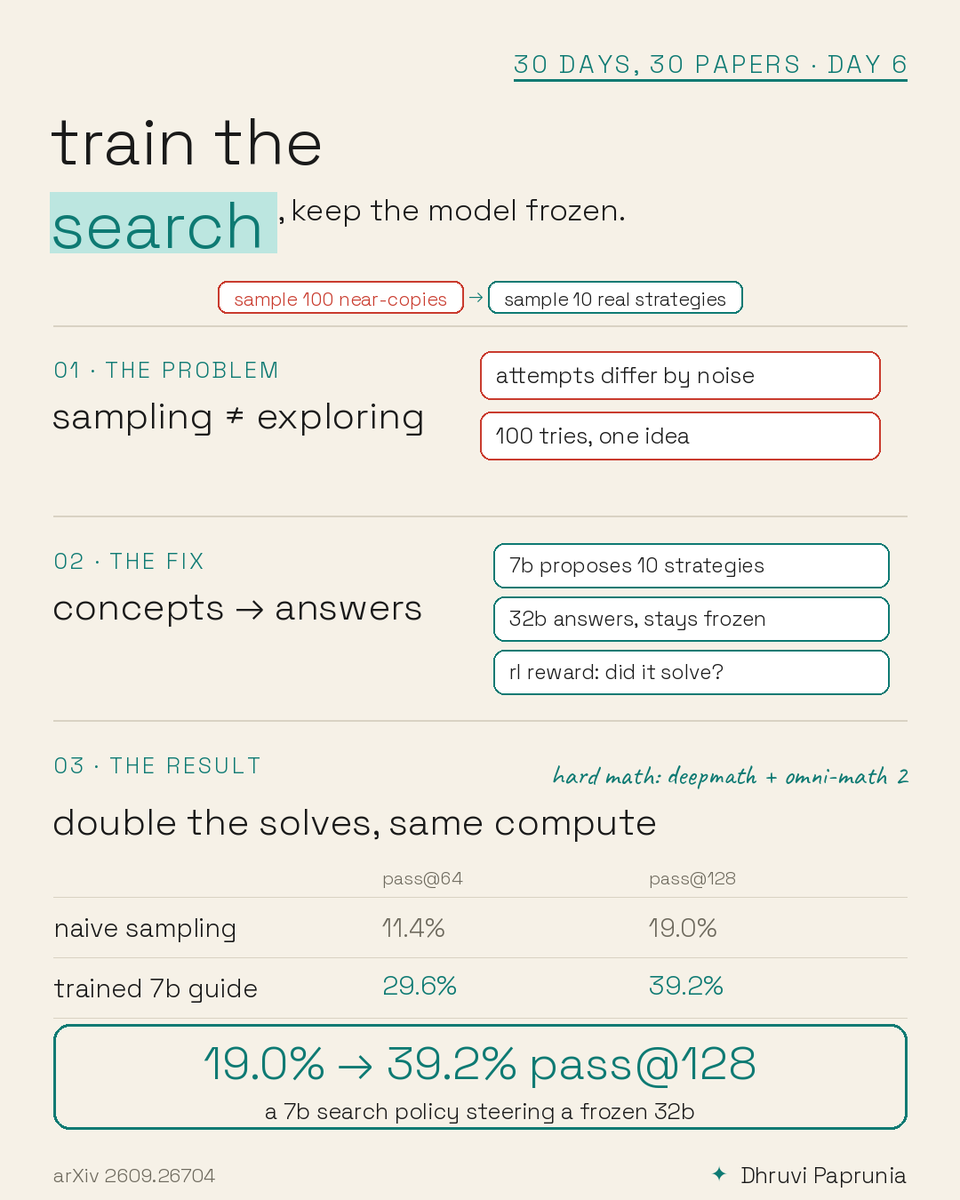
Day 6
Train the search, keep the model frozen
Beyond Repeated Sampling: concepts guide the search
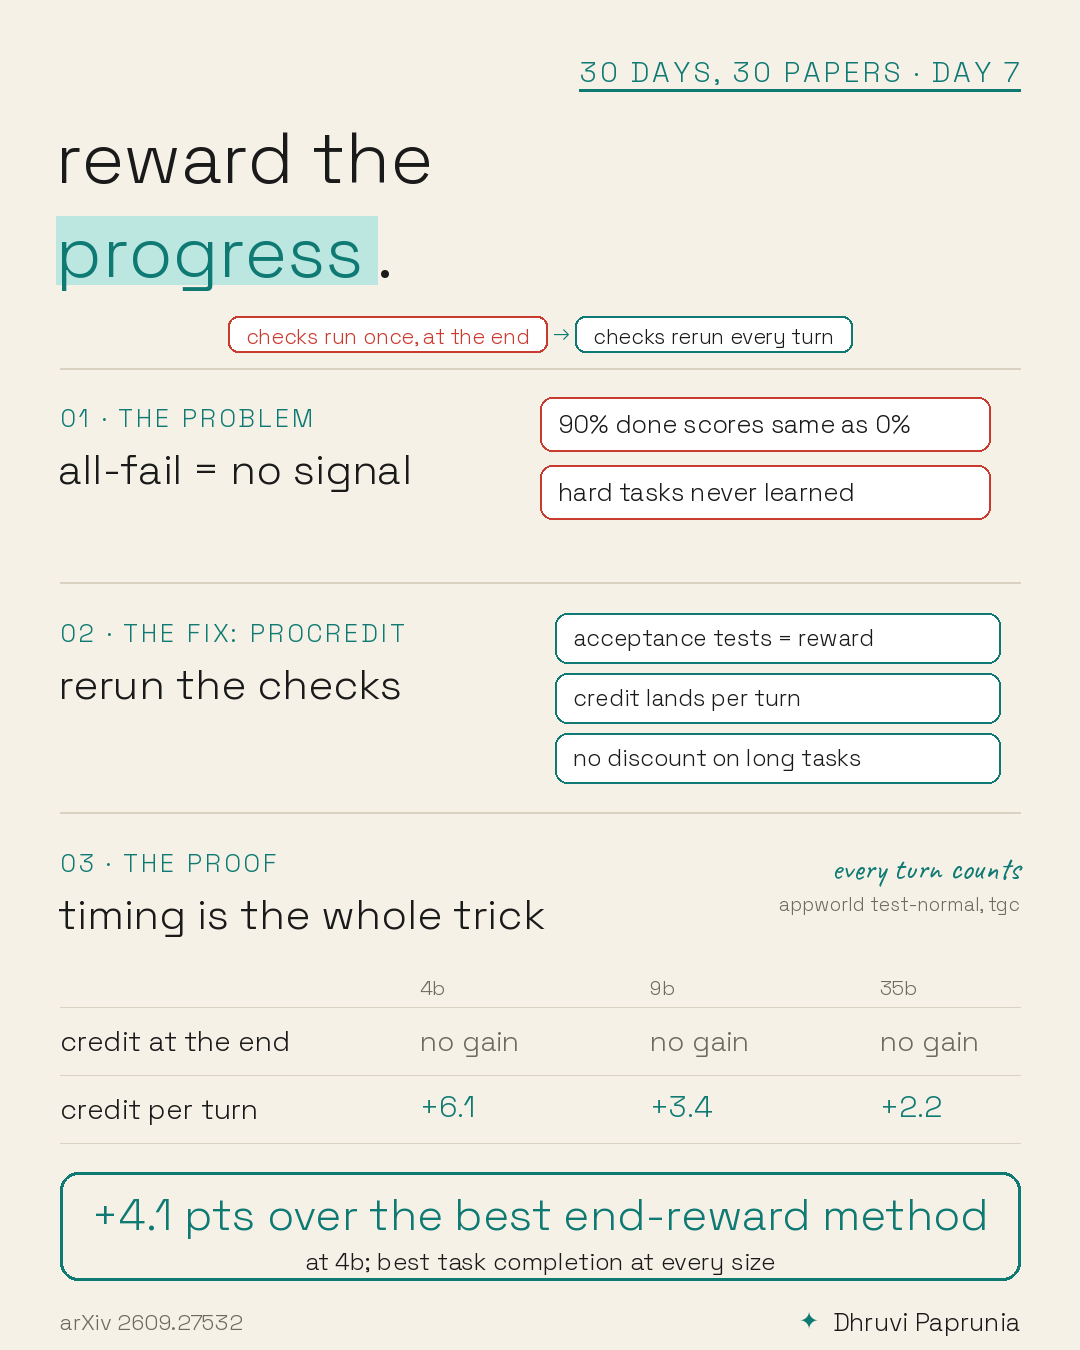
Day 7
Reward the progress
ProCredit: rerun task checks after each turn, so useful progress earns credit.
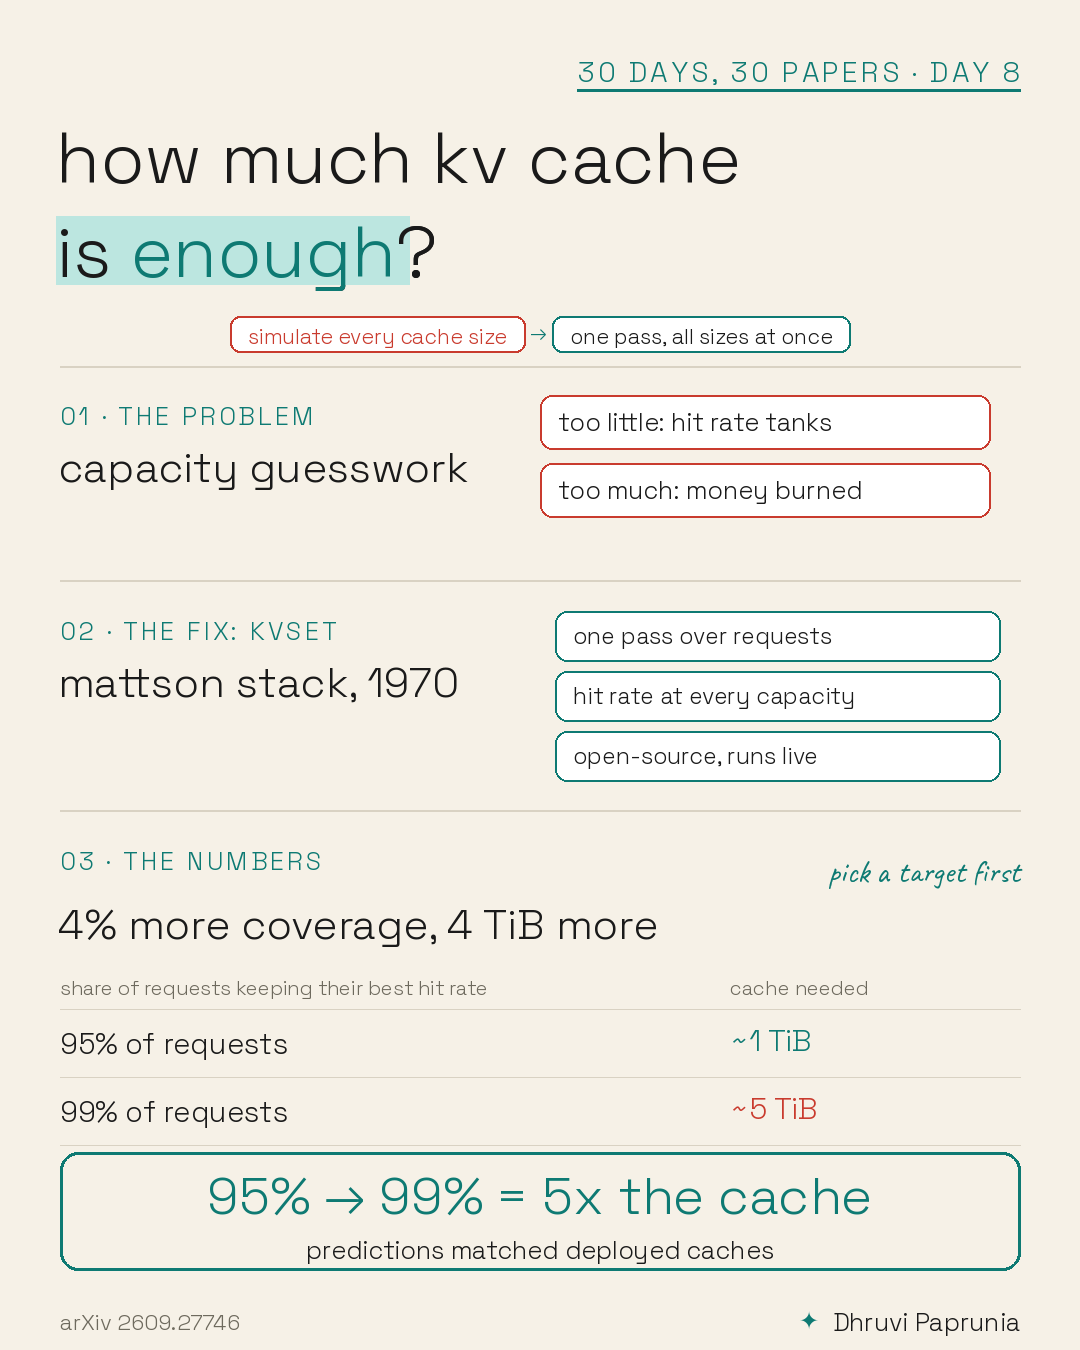
Day 8
How much KV cache is enough?
KVSet: one pass over requests predicts the cache size you need.
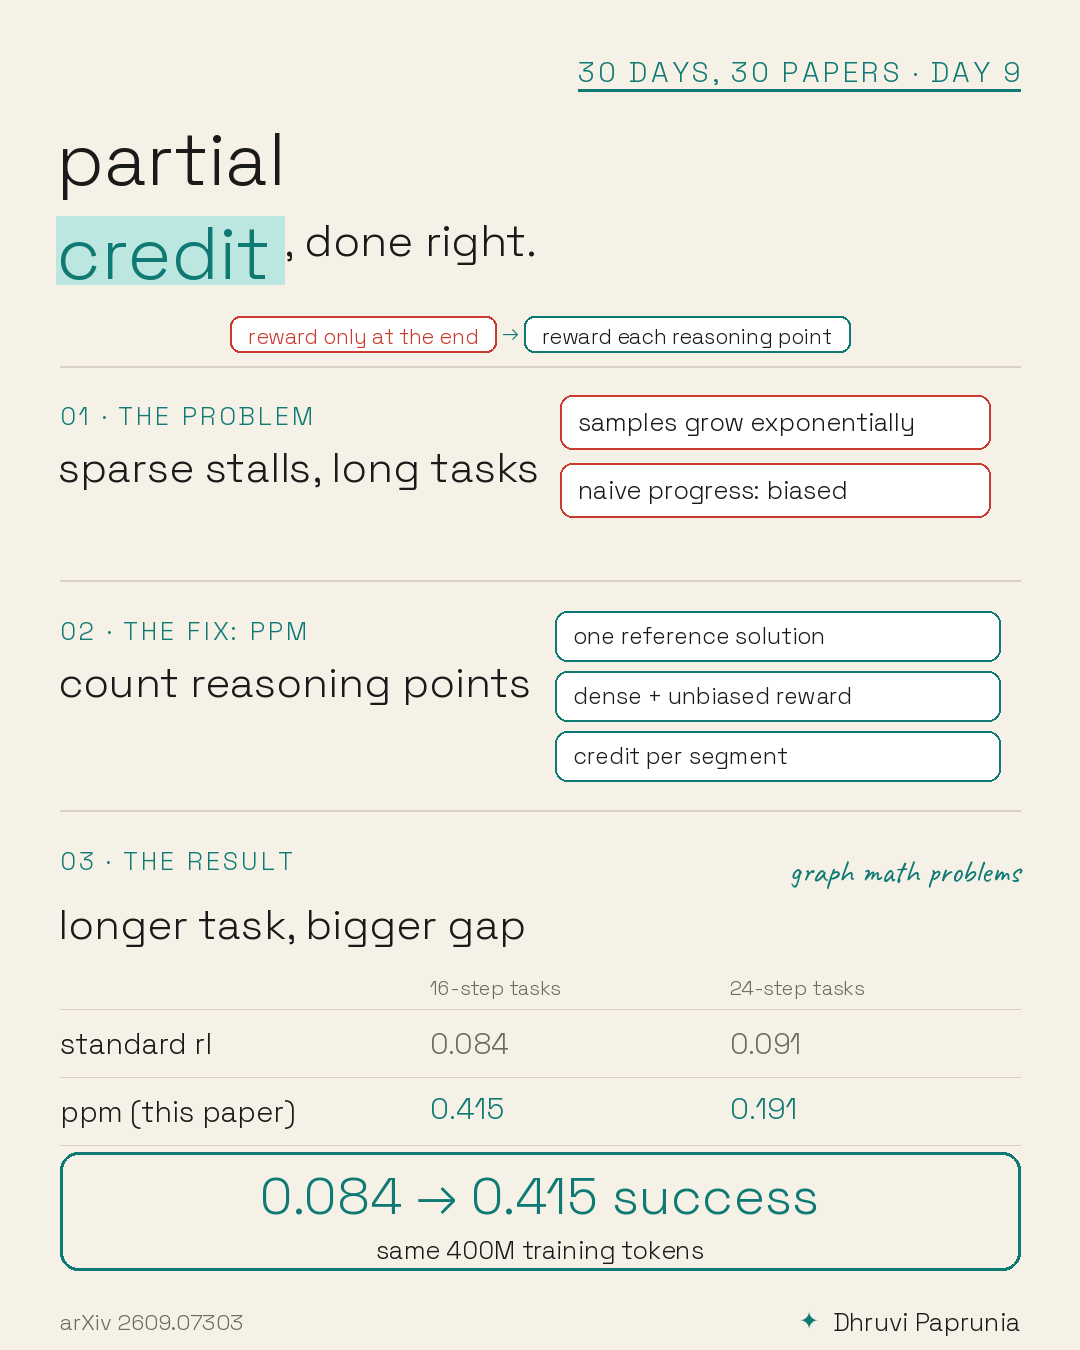
Day 9
Partial credit, done right
Progressive Point Matching: credit milestones from one correct solution.


Day 12
More documents, a harder question
No More Free Lunch: Corpus Task Complexity Matters as Corpora Grow